The systems layer underpinning modern artificial intelligence infrastructure spans inference engines, serving stacks, drivers, and agent runtimes, and it churns continuously as models evolve. To catch entire classes of memory bugs at compile time without sacrificing execution speed, systems engineers have steadily adopted Rust across critical infrastructure. NVIDIA has integrated into this ecosystem by building key components in the language: the Nova Linux driver is written in Rust, NVIDIA Dynamo is built around a Rust core, and NVTX provides native Rust bindings.
Closing the GPU Kernel Gap
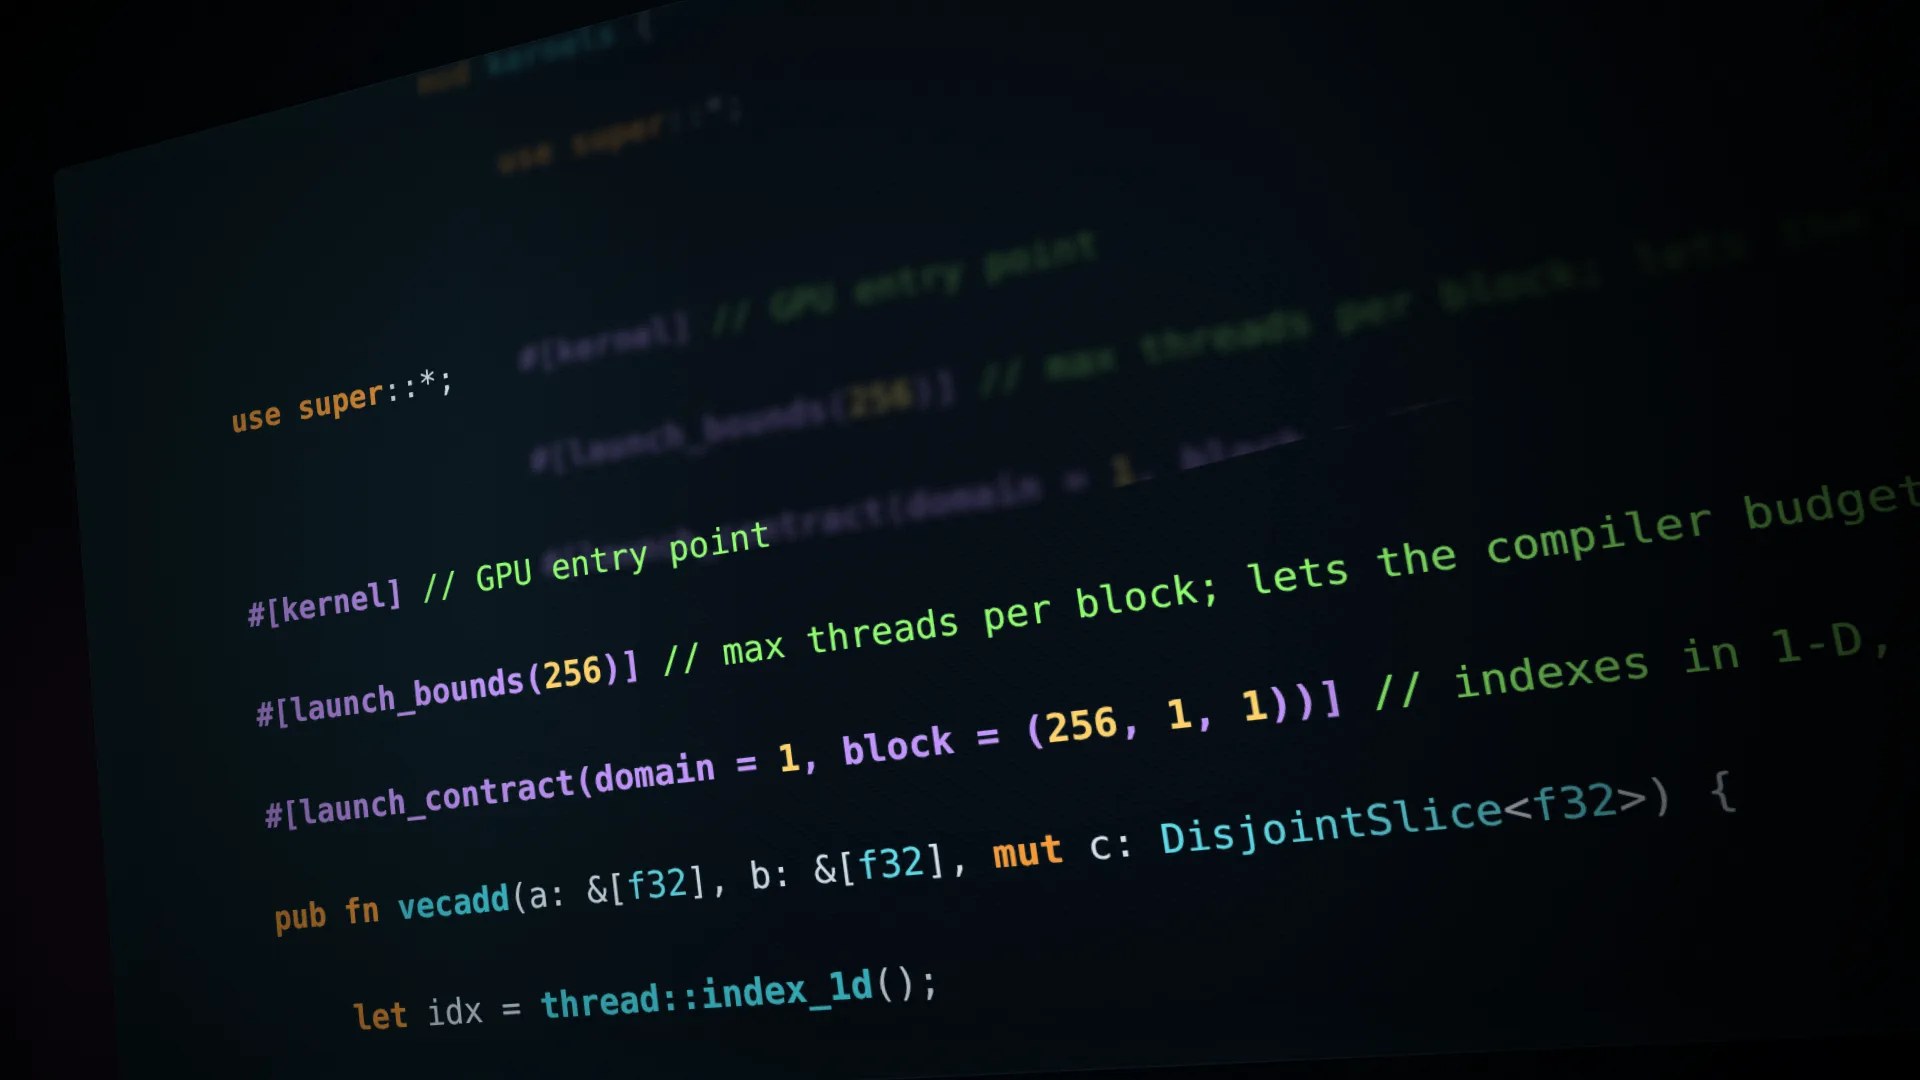
Until recently, GPU execution remained isolated from this end-to-end memory safety. While host code could launch kernels from Rust environments, the kernels themselves were largely written in C++ or wrapped from external components. NVIDIA has announced that it is leaning into native GPU programming in Rust. CUDA Rust closes the technical disconnect across the stack, allowing developers to write GPU kernels directly in Rust and compile them natively to PTX.
NVIDIA CUDA Rust closes the gap by allowing GPU kernels to be written in Rust and compiled natively to PTX.
While CUDA C++ and CUDA Python remain mature enterprise-grade toolchains, NVIDIA plans to grow and mature CUDA Rust through 2027 and beyond. The architecture provides two tracks that mirror existing CUDA paradigms: the traditional SIMT model and the newer Tile programming model.
Tooling Architecture and Enterprise Deployment
On the SIMT track, NVIDIA provides cuda-oxide, which operates as a custom rustc codegen backend. The compiler intercepts the build pipeline, routes functions marked with kernel attributes through Rust MIR, the community Pliron intermediate representation framework, and LLVM IR down to PTX, while passing remaining host routines to the standard backend. Hardware and software requirements for deploying cuda-oxide include Linux, a GPU with compute capability 8.0 or later, CUDA toolkit version 12.x or newer, clang with libclang headers, and a pinned nightly Rust toolchain.
For enterprise engineering teams, this transition signals a pragmatic shift away from legacy C++ vulnerabilities in high-performance serving stacks. By eliminating memory safety bugs at compile time in GPU kernels, organizations can significantly reduce unexpected cluster downtime and cut the engineering overhead of debugging low-level memory corruption without paying a performance tax.