Adapting foundation models traditionally required hiring specialized research teams or paying expensive forward-deployed engineers, but platforms are now emerging to let domain experts retrain open-source systems directly.
Whether developed by OpenAI, Anthropic, or open-source communities, foundational models share a core limitation: they do not learn from mistakes without additional training. Enterprise deployments in specialized sectors like law and finance repeatedly stall against this operational bottleneck. Forward-deployed engineers bill high consulting rates to bridge the gap, turning continuous model maintenance into a recurring line-item expense.
Automating post-training through subject-matter experts shifts this economic structure. Instead of maintaining dedicated machine learning divisions, organizations can collect domain feedback and route it directly into model weights.
Cutting Engineering Overhead with Continual Learning
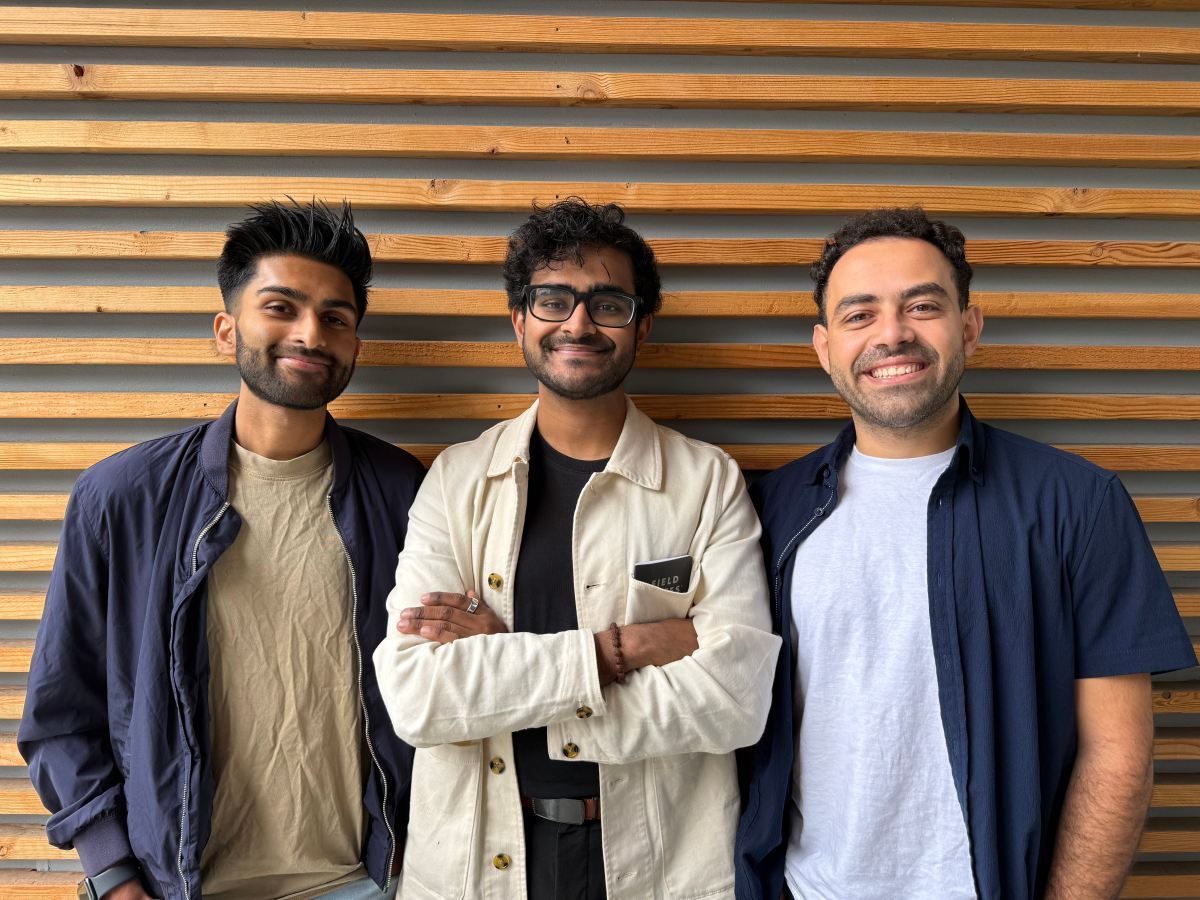
To capitalize on this shift, Trajectory announced a $45 million Series A funding round at a $300 million valuation. The round was led by Sequoia, with participation from Nvidia, Bessemer Venture Partners, and Bain Capital Ventures. Founded about a year ago by three Stanford classmates with backgrounds at Google DeepMind and Apple, the 18-person startup is now making its post-training platform publicly available.
The technical workflow connects an open-source model directly to production applications, capturing operational feedback to retrain the architecture on specialized tasks. This loop allows professionals such as lawyers and doctors to guide model updates without software intermediaries.
"what the economy values is someone who worked on the job for 30 years"
Trajectory co-founder Ronak Malde compared foundational models to a very smart PhD student who is always starting a new job. Enterprise value requires domain experience, which continual learning seeks to instill systematically. Companies such as Harvey and Rogo use the platform to post-train open-source models for specific tasks, including reviewing a particular type of legal contract or valuing a company using a specific methodology. Other customers include Decagon, Mercor, and Nvidia.
How do nontechnical operators manage complex gradient updates without writing machine learning code?
They interact with specialized graphical interfaces designed to abstract the training pipeline. Trajectory co-founder Arjun Karanam, who previously worked on generative foundation models at Apple, noted that the startup has developed an interface that makes post-training more accessible to its nontechnical customers. The startup's staff includes recruits from OpenAI, Stripe, and Netflix, as well as co-founder Michael Elabd, who worked at DeepMind alongside Malde.
Balancing Autonomous Improvement and Safe Oversight
While continual learning shares some similarities with recursive self-improvement, the idea that AI systems can improve their own capabilities, fully autonomous loops present clear operational liabilities. Unsupervised retraining risks runaway drift, unverified outputs, and unintended behavioral degradation.
"keeping humans involved in the training process makes Trajectory's approach safer, since autonomous self-improvement could lead to unintended or even dangerous outcomes."
As Michael Elabd explained, keeping human experts in the training loop protects organizations from the volatility of unconstrained recursive adaptation. Domain professionals determine what good looks like for their organization and can turn that into improvements for their model.
Market competition around post-training infrastructure is expanding rapidly. Trajectory faces direct pressure from Thinking Machines Lab, founded by former OpenAI CTO Mira Murati and behind the fine-tuning tool Tinker, alongside Applied Compute, which was valued at $3.25 billion last month, and Prime Intellect, which helps companies build and train their own AI agents.
Evaluate ongoing consulting fees paid to forward-deployed engineering firms against the infrastructure cost of running open-source models through automated post-training platforms to identify immediate operational savings.
What doesn’t add up
Historically, enterprises bridged this gap by paying hefty consulting invoices to deployed engineers, turning maintenance into a perpetual operational expense. Shifting post-training directly to domain experts via visual interfaces removes technical intermediaries, but places model weight updates in the hands of non-technical staff. This leaves in-house professionals as the sole operational safeguard against unchecked drift and performance degradation. A $45M funding round highlights the industry's shift away from consulting fees toward automated open-source post-training driven directly by domain specialists.